
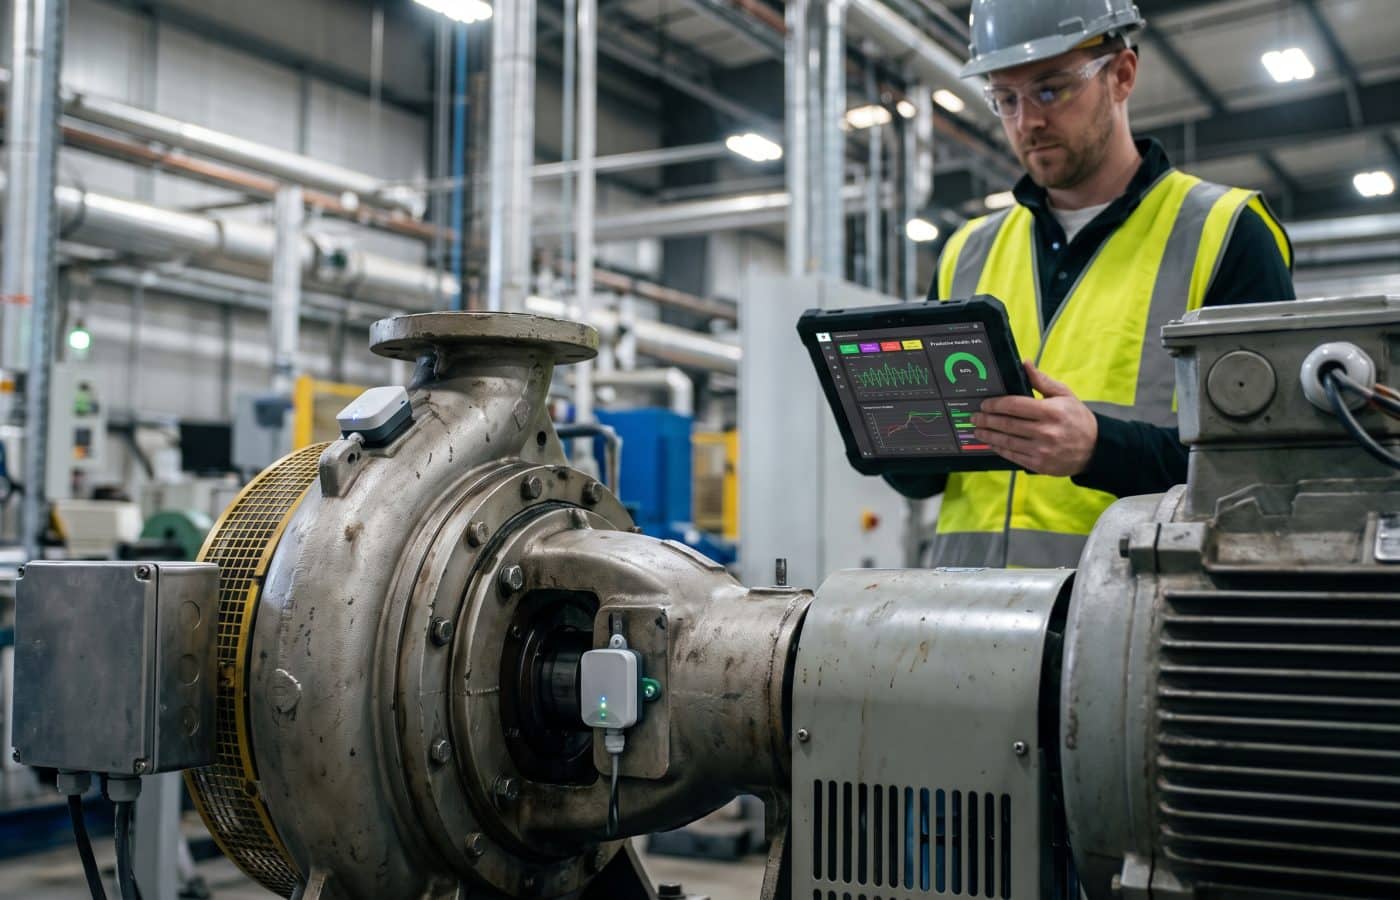
Predictive Maintenance: How Sensors and Data Cut Unplanned Downtime

The worst calls I get as a predictive maintenance engineer come in the middle of the night. A few years back, I got one at 2:40 a.m. from a shift supervisor at a packaging plant. A main drive gearbox had seized, the line was dead, and the replacement was a nine day lead time away. When we pulled the vibration history the next morning, the story was sitting right there in the data. Bearing defect frequencies had been climbing for almost six weeks. Nobody was looking.
That night is the reason I tell every plant manager the same thing: equipment rarely fails without warning. It complains first. Predictive maintenance is simply the discipline of listening to those complaints early enough to do something calm and planned about them, instead of something expensive and frantic.
I have spent most of my career walking plant floors with a data collector, setting alarm limits, arguing with planners about work orders, and occasionally being wrong. This article is what I wish someone had handed me when I started. It covers what predictive maintenance really is, which sensors earn their keep, how the data turns into decisions, and where most programs quietly fall apart.
What Predictive Maintenance Actually Means on the Plant Floor
Most plants run some blend of three maintenance strategies, whether they admit it or not.
Reactive, Preventive, and Predictive Maintenance
Reactive maintenance means you run the asset until it breaks, then fix it. For a cheap, redundant, noncritical pump, that can be a perfectly rational choice.
Preventive maintenance means you service equipment on a calendar or a counter: grease every 30 days, swap the belt every 2,000 hours. It beats pure reaction, but it carries a hidden cost. You replace good parts too early, and you still miss failures that do not respect the calendar. Worse, every time you open a healthy machine, you introduce a chance of a reassembly error.
How Predictive Maintenance Flips the Logic
Predictive maintenance flips the logic. Instead of asking “when is this due,” you ask “what condition is this in right now, and where is it heading?” You measure the physical health of the asset, trend it over time, and act only when the data says a failure is developing. Done right, you replace the bearing that is actually failing and leave the healthy one alone.
People sometimes use condition based maintenance and predictive maintenance as if they mean the same thing. They overlap heavily. In my own shorthand, condition based maintenance is acting on the current state, while predictive maintenance adds the forecasting piece: estimating how much useful life remains so you can schedule the repair into a planned shutdown rather than an emergency one.
Unplanned Downtime: The Real Case for Predictive Maintenance
When a machine fails unexpectedly, the repair invoice is the smallest number in the room. The real cost is lost production, idle labor, scrapped material, overtime, expedited freight on parts, missed shipments, and a customer who starts quietly qualifying a second supplier.
The scale of this is hard to overstate. Siemens’ True Cost of Downtime 2024 report estimated that the world’s 500 largest companies lose roughly $1.4 trillion every year to unplanned downtime, which works out to about 11 percent of their total revenues. That same body of research showed how sharply the hourly figure varies by sector. In the 2022 edition, a lost hour ranged from around $39,000 in fast moving consumer goods facilities to more than $2 million in automotive plants.
There is an interesting wrinkle in that research that matches what I see on site. Downtime costs climbed even though production line failures actually dropped by 23 percent, with large manufacturers averaging about 20 unplanned incidents per facility each month, six fewer than two years earlier. In other words, plants are failing less often, but each failure hurts more, because lines run closer to capacity and there is less slack to recover lost hours.
That is the real argument for predictive maintenance. You are not just saving on parts. You are protecting throughput in an environment where every hour is more valuable than it used to be.
The PF Curve: The Idea Behind Every Predictive Maintenance Program
If you remember one concept from this article, make it the PF curve. It is the backbone of every predictive maintenance program I have built.
From Potential Failure to Functional Failure
Picture a graph with equipment condition on the vertical axis and time on the horizontal. The line starts high and flat while the asset is healthy. At some point, a defect begins. Maybe a tiny spall forms on a bearing race, or a lubricant starts to break down. The first moment that change becomes detectable is point P, potential failure. From there the curve bends downward, slowly at first, then faster, until it hits point F, functional failure, where the machine can no longer do its job.
Why the PF Interval Matters
As one longtime Fluke vibration specialist put it in an ISA InTech feature, most assets travel along a curve from good to progressively worse until they fail completely. The time between P and F is called the PF interval, and it is the window you get to work with. The whole goal of predictive maintenance is to detect P as early as possible, so the PF interval is long enough to plan parts, labor, and a shutdown on your terms. A long interval even gives you time to have an obsolete bracket or guard reproduced through industrial 3D printing or CNC machining, instead of paying for expedited freight.
Different technologies “see” different points along that curve. Roughly in order of how early they catch signs of trouble, the common modalities are oil analysis, ultrasound, vibration monitoring, thermography, and motor testing. By the time you can smell hot grease or hear a bearing scream, you are practically sitting on point F. That is not predictive maintenance. That is a fire drill with a head start.
The Predictive Maintenance Sensors That Do the Heavy Lifting
I get asked constantly which sensor is “the best.” The honest answer is that it depends on the failure mode you are trying to catch. Here is how I think about the main tools.
Vibration Analysis for Predictive Maintenance
Vibration is the workhorse of predictive maintenance, especially on rotating equipment like motors, pumps, fans, gearboxes, and compressors. It picks up the four most common mechanical failure mechanisms: imbalance, misalignment, looseness, and bearing wear. Each of those faults produces a characteristic signature in the frequency spectrum, so a trained analyst can often tell you not just that something is wrong, but what and roughly how bad.
It is also by far the most widely adopted. In a Fluke Reliability webinar survey reported by Plant Services, 82 percent of attendees said they use vibration monitoring or analysis. I am not surprised. When I build a program from scratch, wireless vibration sensors on critical rotating assets are almost always my first move. Mounting matters as much as the sensor, and some of my clients now produce custom mounting bases through additive manufacturing, testing a few shapes first with rapid prototyping before settling on a design.
Airborne and Structure Borne Ultrasound
Ultrasound catches high frequency sounds the human ear cannot hear. It shines at detecting early bearing lubrication problems, compressed air and steam leaks, valve passing, and electrical issues like arcing and tracking. One practical tip from experience: ultrasound guided greasing alone has saved several of my clients from the very common problem of overlubrication, which kills more bearings than people realize.
Infrared Thermography
Thermal cameras are excellent for electrical panels, motor control centers, switchgear, and anything where heat is the symptom. A loose connection on a breaker will glow long before it trips or catches fire. For mechanical faults, though, heat often shows up late on the PF curve, so I treat thermography as a strong complement rather than a front line mechanical tool.
Oil Analysis
For gearboxes, hydraulic systems, and large engines, the oil tells the story of the metal it touches. Wear particle counts, viscosity, water content, and elemental analysis can flag a problem extremely early, sometimes months before vibration notices anything. The catch is sampling discipline. A sample pulled from the wrong port, or from a drain after the oil has settled, is worse than no sample at all, because it gives you false confidence.
Motor Current and Electrical Testing
Motor circuit analysis and current signature analysis look at the electrical side: winding insulation breakdown, rotor bar defects, supply imbalance. In plants with hundreds of motors, this is how you find the slow electrical problems that vibration might miss.
Process Data You Already Own
Here is something many plants overlook. Your control system and your MES are already logging pressures, flows, temperatures, amperage, and speeds. A pump whose discharge pressure is drifting down while motor current creeps up is telling you about impeller wear or recirculation, and you did not need to buy a single new sensor to see it. Some of the best predictive maintenance wins I have seen came from simply trending historian data that had been sitting unused for years.
Turning Predictive Maintenance Data Into Decisions
Sensors produce numbers. Numbers are not insight. The step between them is where programs succeed or fail.
Establish Baselines First
Every asset has its own normal. A fan on a rigid concrete pad behaves differently than the same model mounted on a steel mezzanine. Before you trust any alarm, collect enough healthy data to know what “good” looks like for that specific machine. International standards such as ISO 20816 give general vibration severity guidance, but your own trend line is almost always more useful than a generic chart.
Set Alarms That People Will Actually Respect
The fastest way to kill a predictive maintenance program is alarm fatigue. If technicians get forty warnings a day and thirty eight of them are noise, they will stop looking, and they will be right to. I set alarms in tiers, start conservatively, and tune them over the first few months. A smaller number of trustworthy alerts beats a flood of anxious ones every single time.
Edge Processing and Connectivity
Modern wireless sensors often do some of the math on the device itself, sending summary values like overall velocity or a bearing condition indicator rather than raw waveforms around the clock, often to a cloud analytics platform. That saves battery and bandwidth. For your most critical assets, though, keep the ability to pull a full high resolution waveform on demand. When an analyst needs to confirm a diagnosis, the summary number is rarely enough. Also, every wireless gateway is a new connection on the plant network, so hold it to the same OT cybersecurity standards as any other device on the floor.
Where Machine Learning Fits in Predictive Maintenance
There is a lot of excitement about AI in predictive maintenance, and some of it is earned. Anomaly detection models are genuinely good at noticing when a machine drifts from its own learned pattern, especially across dozens of variables at once. But I am going to be blunt: a model does not replace understanding the failure mode. When an algorithm flags an anomaly, a person still needs to decide whether it is a developing bearing fault, a process change, or a sensor that came loose from its mount. The best setups I have worked with use machine learning as a tireless first filter and human analysts as the final judge.
Close the Loop in the CMMS
An alert that never becomes a work order is just trivia. The ISA piece makes the same point: a computerized maintenance management system is one of the most practical ways to manage the volume of data and findings that condition monitoring produces. Every confirmed finding should create a work order, and every completed repair should feed back what was actually found inside the machine. That feedback is how your alarm limits and your analysts get sharper over time.
What Predictive Maintenance Numbers Say, and How Skeptical to Be
You will see a lot of impressive percentages quoted for predictive maintenance. Some are solid, some are recycled marketing. Here is how I read the most common ones.
The McKinsey Benchmark
McKinsey has reported that predictive maintenance can cut machine downtime by 30 to 50 percent and extend machine life by 20 to 40 percent. Those are broad ranges, and where your plant lands depends heavily on where you are starting from. A site running mostly reactive will see bigger gains than one with a mature preventive program.
The Department of Energy Figures
The United States Department of Energy has offered more conservative numbers in its operations and maintenance guidance. The DOE’s Operations and Maintenance Best Practices guide, Release 3.0, estimates that a predictive maintenance program can deliver an 8 to 12 percent reduction in maintenance costs compared with a typical preventive program. I actually like quoting that figure to finance teams, because it is modest and defensible. The bigger financial payoff usually comes from avoided downtime, not from the maintenance budget line.
The Numbers to Handle With Care
You will also run into a widely shared claim that predictive maintenance reduces breakdowns by 70 percent and raises productivity by 25 percent. It appears in a Deloitte Analytics Institute position paper, but if you trace that paper’s footnote, it leans on an older trade article rather than a controlled study. I do not throw it out, but I would never build a business case on it alone.
Build Your Predictive Maintenance Case With Your Own Data
My advice is simple. Use published benchmarks to get leadership interested, then build the real case with your own plant data. Pull the last two years of unplanned downtime events, put a cost on each one, and identify which were caused by failure modes that monitoring could have caught. That number will be far more persuasive than any consultant’s headline.
Where Predictive Maintenance Programs Go Wrong
I have been brought in to rescue enough struggling programs to see the same patterns repeat.
Sensors Everywhere, Priorities Nowhere
A plant buys several hundred sensors, bolts them onto everything, and drowns in data. Start with a criticality ranking. Which assets, if they failed tonight, would stop production, create a safety hazard, or cost the most to repair? Monitor those first.
No One Owns the Data
Predictive maintenance needs a named person, or a small team, whose job is to review trends and make calls. When it becomes “everyone’s responsibility,” it quietly becomes no one’s.
Findings That Never Get Fixed
I once audited a site with a beautiful dashboard full of red alarms that had been red for months. The analysts had done their job. Planning and scheduling had not, and the parts needed for most repairs had never even been requested through the ERP. If your organization cannot act on a finding within the PF interval, the monitoring is wasted.
Ignoring the Basics
Predictive maintenance does not fix poor lubrication practices, bad alignment, or soft foot. It just tells you, repeatedly, that those problems exist. The plants that get the most out of monitoring use it to drive precision maintenance habits, so failures start less often in the first place.
Treating It as an IT Project
Connectivity and software matter, but this is fundamentally a reliability engineering discipline. Keep maintenance and reliability people in the driver’s seat, with IT, or an outside provider of manufacturing IT services, as a strong partner.
A Predictive Maintenance Roadmap for Your First 12 Months
If you are starting from zero, here is the sequence I usually recommend.
Months One and Two: Decide What Matters
Build an asset criticality list. Review your downtime history and pick the 10 to 20 assets that hurt most when they fail. For each one, list the likely failure modes and match them to a monitoring technology.
Months Three and Four: Start Small and Visible
Deploy monitoring on a pilot group, often a single line or one class of asset like critical pumps or fans. Collect baseline data. Train at least one person to a recognized vibration analyst level so you have in house judgment.
Months Five Through Eight: Tune and Prove
Adjust alarm limits, connect findings to the CMMS, and document every catch. When the program finds a developing fault and the team fixes it during planned downtime, write it up with real costs avoided. These “saves” are the currency that funds expansion.
Months Nine Through Twelve: Scale With Discipline
Add assets in waves based on criticality. Bring in additional technologies, like oil analysis on gearboxes or thermography on electrical gear, where the failure modes call for them. Review results quarterly with operations, not just maintenance.
Notice what is missing from that plan: a giant upfront purchase. The programs that last are the ones that earn their budget with documented wins.
The People Side of Predictive Maintenance
Technology gets the headlines, but culture decides whether predictive maintenance sticks. Technicians who have spent twenty years fixing things when they break can feel like a sensor is second guessing their experience. I have found the opposite approach works far better: treat their experience as the best training data you have. The mechanic who can tell a bad bearing by putting a screwdriver to his ear understands failure modes intuitively. Give that person the tools and the data, and he often becomes your strongest analyst.
Operators matter too. They are the ones who notice a new noise or a smell at 3 a.m. Make it easy for them to log observations, and make sure someone responds. Nothing kills engagement faster than reporting a problem and hearing nothing back.
And celebrate the quiet wins. A failure that never happened is invisible by nature. If you do not tell the story of the gearbox you caught six weeks early, nobody will know the program did anything at all.
The Bottom Line on Predictive Maintenance
Predictive maintenance is not magic, and it is not a product you can simply buy. It is a way of running a plant where equipment condition drives decisions instead of the calendar or the crisis. The sensors and analytics have gotten dramatically cheaper and smarter in the last decade, much like the wider push toward industrial automation, which means plants of almost any size can now do what used to be reserved for refineries and power stations.
Start with the assets that hurt most. Learn what normal looks like. Trust your data, but keep a skilled human in the loop. Close every finding with a work order. Do those things consistently, and the 2:40 a.m. phone calls become rare enough that you will actually remember the last one.
Frequently Asked Questions About Predictive Maintenance
What is predictive maintenance in simple terms?
Predictive maintenance means monitoring the actual condition of equipment with sensors and data, then scheduling repairs only when that data shows a failure is developing. It sits between waiting for breakdowns and servicing on a fixed calendar. For a deeper look at how condition data maps to the failure timeline, see the ISA InTech article on the PF curve.
How much does unplanned downtime really cost?
It varies enormously by industry. Siemens research places the combined loss for the world’s 500 largest companies at around $1.4 trillion a year, with hourly costs ranging from tens of thousands of dollars in consumer goods to millions in automotive. See the summary of the 2024 report.
Which sensor should I start with for predictive maintenance?
For rotating equipment, vibration monitoring is usually the best first investment because it detects imbalance, misalignment, looseness, and bearing wear. Add oil analysis, ultrasound, or thermography based on the failure modes of each asset. Plant Services covers the main modalities here.
What results can a predictive maintenance program realistically deliver?
McKinsey reports downtime reductions of 30 to 50 percent and machine life extensions of 20 to 40 percent, while the DOE offers a more conservative 8 to 12 percent maintenance cost saving over preventive programs. Your results depend on your starting point. See McKinsey’s analysis.
Is predictive maintenance worth it for smaller plants?
Usually yes, if you start with your most critical assets rather than monitoring everything. Wireless sensors and cloud analytics have lowered the entry cost considerably. Deloitte’s overview of predictive maintenance in the digital supply network is a useful planning read.
Does AI replace maintenance technicians in predictive maintenance?
No. Machine learning is excellent at spotting anomalies across large volumes of data, but people are still needed to diagnose the cause, plan the repair, and do the work. The strongest programs pair automated detection with experienced analysts. For more on how analytics and people work together, see Fluid Life’s summary of predictive maintenance benchmarks.
References
- Siemens. The True Cost of Downtime 2024 (white paper listing via Automation.com)
- AEMT. The True Cost of Downtime 2024: A Comprehensive Analysis
- Senseye (Siemens). The True Cost of Downtime 2022
- ISA InTech. Improving Maintenance by Adopting a PF Curve Method
- Plant Services. Modalities Impacting the PF Curve
- New Equipment Digest. Understanding PF Curve Modalities and Inherent Availability, Part 2
- McKinsey & Company. Manufacturing: Analytics Unleashes Productivity and Profitability
- Deloitte Insights. Making Maintenance Smarter: Predictive Maintenance and the Digital Supply Network
- Deloitte Analytics Institute. Predictive Maintenance Position Paper
- American Society for Health Care Engineering. Benefits of Predictive Maintenance (citing the DOE O&M Best Practices Guide, Release 3.0)
- Fluid Life. Plant Failures Warning (summary of McKinsey and DOE predictive maintenance benchmarks)